The decision to invest in AI infrastructure centers on GPUs. But GPU compute efficiency is ultimately gated by the network connecting them. In large-scale AI training clusters, the network fabric is not infrastructure support — it is a primary determinant of how much of your GPU investment actually delivers productive compute cycles.
A suboptimal network can reduce GPU utilization by up to 50% during the compute-exchange-update phase of distributed training. When GPU clusters cost thousands of dollars per hour to operate, network inefficiency is a direct revenue loss.
Why the Network is the AI Bottleneck
Modern AI training uses distributed data parallelism: multiple GPU nodes process data simultaneously and periodically synchronize gradients. The synchronization step — the All-Reduce operation — requires all GPUs to exchange gradient data through the network simultaneously. This creates extreme traffic bursts that expose every weakness in the fabric:
- Packet loss — RoCEv2 (RDMA over Converged Ethernet) is loss-sensitive. A single dropped packet triggers retransmission that stalls the entire GPU collective operation until the packet is recovered.
- Latency spikes — jitter during All-Reduce operations extends Job Completion Time (JCT) proportionally to the number of GPUs in the cluster.
- Congestion spreading — without proper flow control, congestion on one link spreads to others through head-of-line blocking, degrading the entire fabric.
The Three AI Fabric Design Decisions
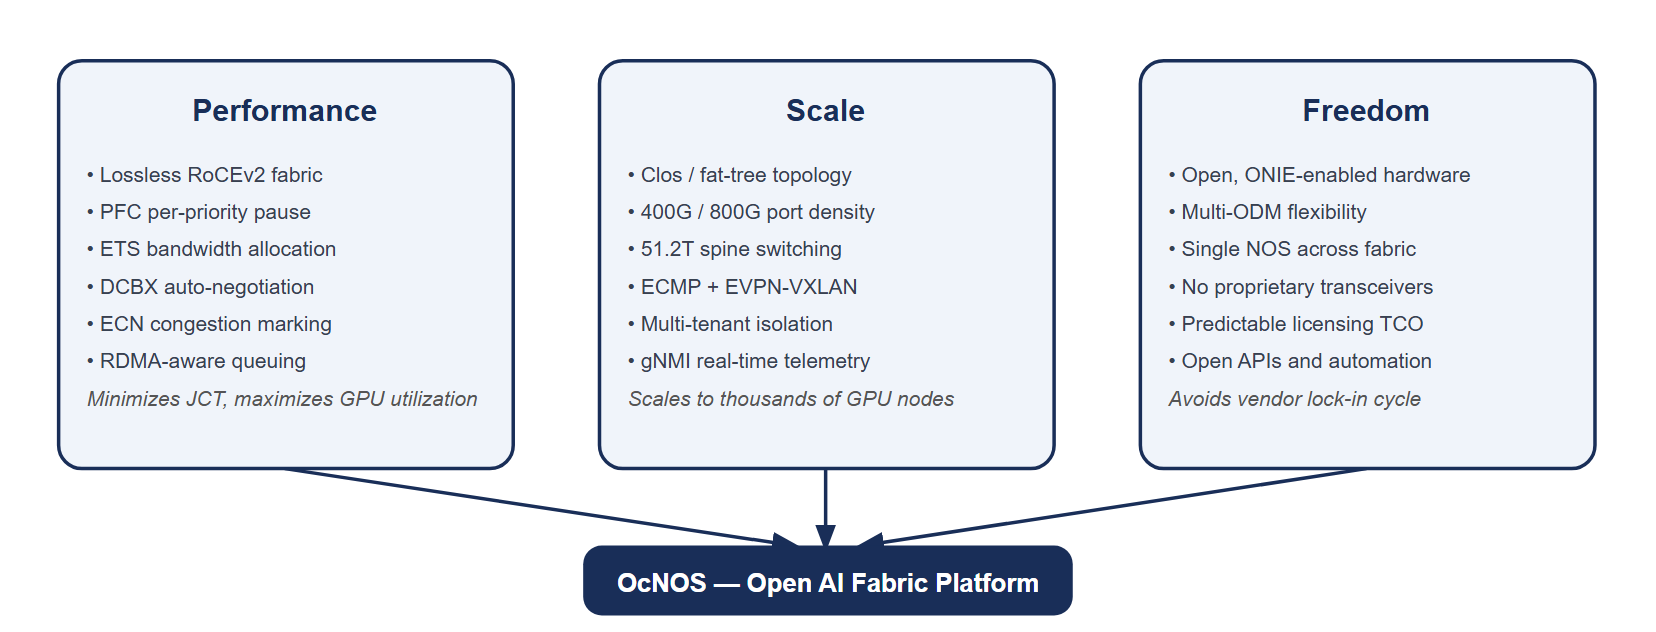
OcNOS AI Fabric Capabilities
OcNOS 7.0 delivers a complete lossless AI fabric stack on Broadcom Tomahawk 5-based open hardware:
- Priority-Based Flow Control (PFC) — per-priority pause frames prevent RoCEv2 packet drops at the switch level
- Enhanced Transmission Selection (ETS) — allocates guaranteed bandwidth to RoCEv2 traffic classes (typically 70–80% of fabric bandwidth)
- DCBX — automatically negotiates PFC and ETS parameters with GPU servers, eliminating manual server-side configuration
- 显式拥塞通知(ECN) — signals congestion to senders before queues fill, enabling proactive rate reduction
- EVPN-VXLAN multi-tenancy — isolates multiple AI workloads or tenants on the same physical fabric
Open vs. Proprietary AI Fabric: TCO at Scale
| Factor | Proprietary (Arista, Cisco) | OcNOS on Open Hardware |
|---|---|---|
| Spine switch (51.2T, 64x800G) | $150K–$250K per switch | $60K–$100K per switch |
| NOS licensing | Per-feature or bundle; complex | All-inclusive per platform |
| Transceiver lock-in | Often required for warranty | Third-party optics supported |
| Hardware vendor flexibility | 单一厂商 | UfiSpace, Edgecore, Celestica, others |
| Automation interfaces | Vendor-specific APIs | gNMI, NETCONF, OpenConfig, Ansible |
For a 100-node GPU cluster requiring 10 spine switches, the hardware cost difference alone is $500K–$1.5M over a 3-year lifecycle.
- OcNOS 7.0 for Data Centers — AI Fabric Details
- AI Fabric Solutions
- OcNOS-DC Product Page
- 联系 IP Infusion
IP Infusion Engineering Team
深入了解,随身带走。
产品数据手册,以及内容比本页更为深入的简明技术下载资料。
OcNOS-DC 数据手册
完整的 OcNOS-DC 规格:EVPN-VXLAN 与 Ethernet for AI 功能集、软件 SKU、支持的硬件平台,以及解决方案订购指南。
获取数据手册
OcNOS 800G 无损 AI Fabric
基于 Tomahawk 5 spine 的无损 RoCEv2 fabric:SKU 等级、经过认证的平台和部署架构。
获取简报
EVPN-VXLAN 数据中心网络
基于 EVPN-VXLAN 的 leaf-spine 数据中心 fabric:每租户一个 VRF 和多个 VNI、EVPN 多归属、BGP unnumbered 和 route-target 过滤。
获取简报OcNOS-DC 数据手册
表单简短。提交后您的 PDF 将立即在新标签页中打开。
✓ 正在新标签页中打开您的 PDF……
如果未能自动打开,请使用下方链接。
OcNOS 800G 无损 AI Fabric
表单简短。提交后您的 PDF 将立即在新标签页中打开。
✓ 正在新标签页中打开您的 PDF……
如果未能自动打开,请使用下方链接。
EVPN-VXLAN 数据中心网络
表单简短。提交后您的 PDF 将立即在新标签页中打开。
✓ 正在新标签页中打开您的 PDF……
如果未能自动打开,请使用下方链接。