The decision to invest in AI infrastructure centers on GPUs. But GPU compute efficiency is ultimately gated by the network connecting them. In large-scale AI training clusters, the network fabric is not infrastructure support; it is a primary determinant of how much of your GPU investment actually delivers productive compute cycles.
A suboptimal network can reduce GPU utilization by up to 50% during the compute-exchange-update phase of distributed training. When GPU clusters cost thousands of dollars per hour to operate, network inefficiency is a direct revenue loss.
Why the Network is the AI Bottleneck
Modern AI training uses distributed data parallelism: multiple GPU nodes process data simultaneously and periodically synchronize gradients. The synchronization step (the All-Reduce operation) requires all GPUs to exchange gradient data through the network simultaneously. This creates extreme traffic bursts that expose every weakness in the fabric:
- Packet loss: RoCEv2 (RDMA over Converged Ethernet) is loss-sensitive. A single dropped packet triggers retransmission that stalls the entire GPU collective operation until the packet is recovered.
- Latency spikes: jitter during All-Reduce operations extends Job Completion Time (JCT) proportionally to the number of GPUs in the cluster.
- Congestion spreading: without proper flow control, congestion on one link spreads to others through head-of-line blocking, degrading the entire fabric.
The Three AI Fabric Design Decisions
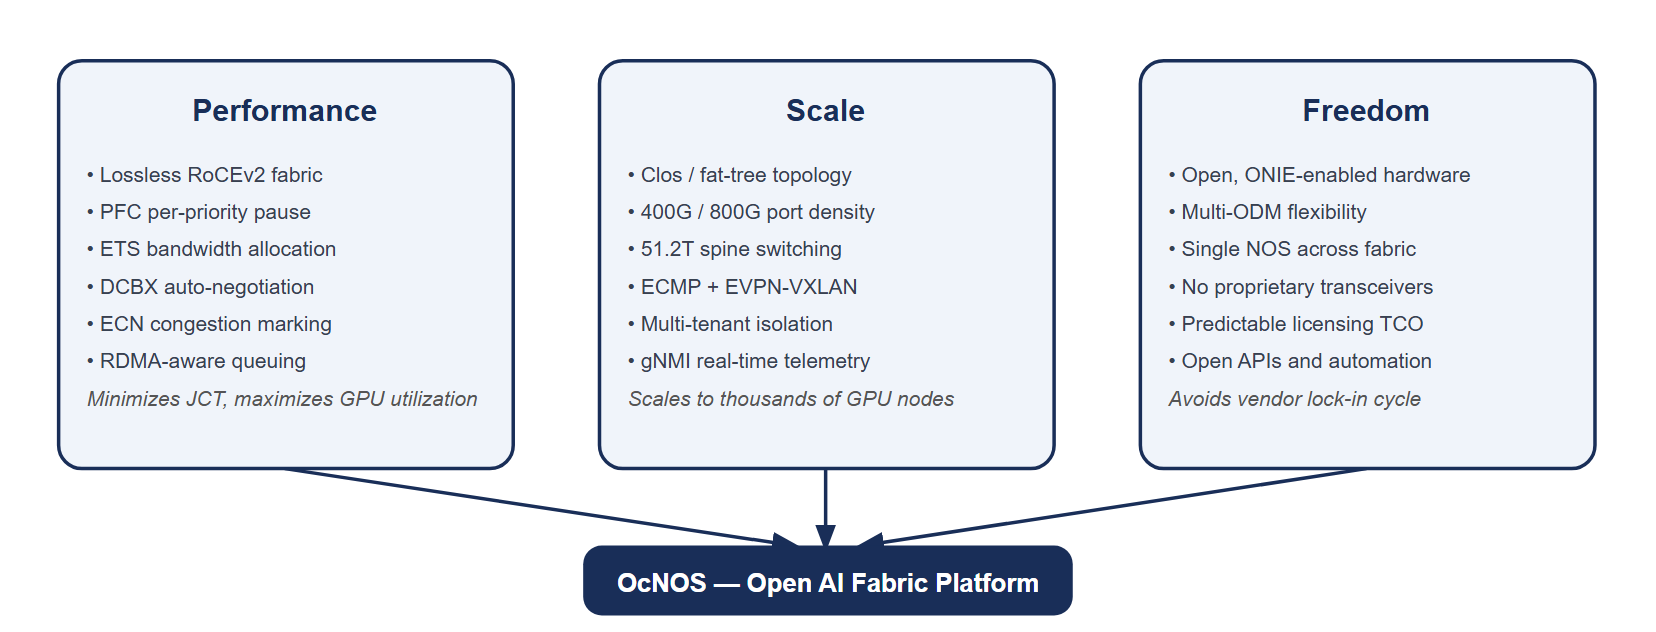
OcNOS AI Fabric Capabilities
OcNOS 7.0 delivers a complete lossless AI fabric stack on Broadcom Tomahawk 5-based open hardware:
- Priority-Based Flow Control (PFC): per-priority pause frames prevent RoCEv2 packet drops at the switch level
- Enhanced Transmission Selection (ETS): allocates guaranteed bandwidth to RoCEv2 traffic classes (typically 70-80% of fabric bandwidth)
- DCBX: automatically negotiates PFC and ETS parameters with GPU servers, eliminating manual server-side configuration
- Explicit Congestion Notification (ECN): signals congestion to senders before queues fill, enabling proactive rate reduction
- EVPN-VXLAN multi-tenancy: isolates multiple AI workloads or tenants on the same physical fabric
Open vs. Proprietary AI Fabric: TCO at Scale
| Factor | Proprietary (Arista, Cisco) | OcNOS on Open Hardware |
|---|---|---|
| Spine switch (51.2T, 64x800G) | $150K-$250K per switch | $60K-$100K per switch |
| NOS licensing | Per-feature or bundle; complex | All-inclusive per platform |
| Transceiver lock-in | Often required for warranty | Third-party optics supported |
| Hardware vendor flexibility | Proveedor único | UfiSpace, Edgecore, Celestica, others |
| Automation interfaces | Vendor-specific APIs | gNMI, NETCONF, OpenConfig, Ansible |
For a 100-node GPU cluster requiring 10 spine switches, the hardware cost difference alone is $500K-$1.5M over a 3-year lifecycle.
- OcNOS 7.0 for Data Centers: AI Fabric Details
- AI Fabric Solutions
- OcNOS-DC Product Page
- Contactar con IP Infusion
IP Infusion Engineering Team
Profundice. Llévelo consigo.
El datasheet del producto y descargas técnicas y breves que profundizan más que esta página.
Datasheet de OcNOS-DC
Especificación completa de OcNOS-DC: el conjunto de funciones EVPN-VXLAN y Ethernet for AI, los SKU de software, las plataformas de hardware compatibles y la guía de pedido de la solución.
Obtener el datasheet
AI Fabric sin pérdidas de 800G con OcNOS
Fabric RoCEv2 sin pérdidas con spines Tomahawk 5: niveles de SKU, plataformas cualificadas y arquitectura de despliegue.
Obtener el brief
Fabric DC EVPN-VXLAN
Fabric de centro de datos leaf-spine sobre EVPN-VXLAN: una VRF y VNI por inquilino, multihoming EVPN, BGP unnumbered y filtrado por route target.
Obtener el briefDatasheet de OcNOS-DC
Formulario rápido. Su PDF se abre en una pestaña nueva inmediatamente después de enviarlo.
✓ Abriendo su PDF en una pestaña nueva…
Si no se ha abierto, utilice el enlace de abajo.
AI Fabric sin pérdidas de 800G con OcNOS
Formulario rápido. Su PDF se abre en una pestaña nueva inmediatamente después de enviarlo.
✓ Abriendo su PDF en una pestaña nueva…
Si no se ha abierto, utilice el enlace de abajo.
Fabric DC EVPN-VXLAN
Formulario rápido. Su PDF se abre en una pestaña nueva inmediatamente después de enviarlo.
✓ Abriendo su PDF en una pestaña nueva…
Si no se ha abierto, utilice el enlace de abajo.