乙太網路是否已為 AI 做好準備?證據已在供貨
The four sections below each answer it with something already in production, not a roadmap: shipping 800G silicon, a hyperscale Ethernet cluster, the closed utilization gap, and a moving standard. Every figure is sourced to a hardware spec or a named third party.
The hardware is here
Open 800G AI switches are not a preview. They are on the hardware compatibility list and shipping. OcNOS-DC runs on Broadcom Tomahawk 5 and Tomahawk 4 platforms from Edgecore and UfiSpace, the same merchant silicon the rest of the industry builds AI fabrics on, so you keep switch, NIC, and GPU choices open. These are on-chip, shared-buffer switches built for lossless RDMA at 800G.
800G spine and leaf
Edgecore AIS800-64D and UfiSpace S9321-64E / S9321-64EO, the latter with 400G ZR+ coherent ports. On-chip shared buffering for lossless RoCEv2. Both platforms are HCL-listed.
400G leaf
Edgecore AS9736-64D for 400G leaf roles and smaller fabrics, on the same lossless RoCEv2 primitives as the 800G tier, breaking out to 100G and 25G.
Supported as a system
藉助 OcNOS Systems,一份 IP Infusion 合約即可同時涵蓋 OcNOS-DC 與經過認證的交換器硬體,因此整個 fabric 只需一個 TAC 和一份 SLA。
The scale is proven
The most common objection to Ethernet for AI is scale, and the industry has already answered it in production. You do not have to take a switch vendor's word for it, because the hyperscalers publish their designs.
Meta 在基於乙太網路的 fabric 上執行 24,576 GPU 的 AI 訓練叢集。 這是業界的證明:標準乙太網路如今已在正式環境中大規模承載超大規模 AI 訓練。它是回答「是否已就緒」這一問題的參照點:fabric 不是瓶頸。
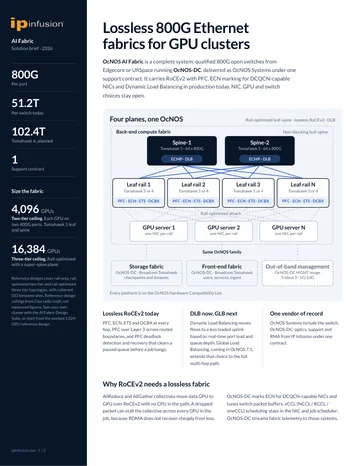
在 OcNOS-DC 上,同樣的物理規律也適用於您的構建。雙層 Tomahawk 5 設計在每 GPU 800G、1:1 收斂比下可達 4,096 個 GPU。超出後,super-spine 層可擴展至 16,000 個以上。請參閱 AI fabric 拓撲 for the port math behind each tier.
The utilization gap is closed
The old knock on Ethernet was load balancing: standard ECMP pins each large flow to one uplink, so during a collective some links jam while parallel paths sit idle and the sync waits on the slowest link. That gap is now closed on the same switches, and the proof is a hardware feature, not a promise.
How the gap closes. Static ECMP pins each large flow to one uplink; dynamic load balancing rebinds flows on real-time congestion so a well-run AI fabric targets utilization in the 90 percent range on Tomahawk 4 and Tomahawk 5, on the same switches, with no extra uplinks. OcNOS-DC ships DLB on those platforms.
DLB deep-dive →The standard is moving
適用於 AI 的乙太網路並非單一廠商的專有岔路。 Ultra Ethernet Consortium 發布了 UEC 1.0 規範,使乙太網路傳輸適配 AI 與 HPC 的規模,並獲得晶片、NIC 與雲端運算企業的支援。IP Infusion 是 Ultra Ethernet Consortium 的 成員 。
UEC 1.0 定義了一種多路徑傳輸,將一條流分散到多條路徑上,而不是固定在單個 ECMP 雜湊上,這一端點行為執行於支援 UEC 的 NIC 上。OcNOS-DC 如今已在 Broadcom Tomahawk 4 和 Tomahawk 5 交換器上,於生產環境中執行基於 PFC、ECN 標記和 DLB 的無損 RoCEv2。DCQCN 執行於 NIC 上,並對這些 ECN 標記做出反應。請參閱 Ultra Ethernet 深度解析 for how packet spray and multi-path RDMA change the transport.
What OcNOS-DC ships today
Underneath the proof points is a fabric you can turn up now. OcNOS-DC provides the lossless Ethernet fabric that RoCEv2 requires, so your training collectives move GPU-to-GPU over RDMA without loss. DCQCN is the end-to-end loop between the NICs and the switches; the switch role in that loop is early ECN marking. Every primitive below is verified and shipping, not a roadmap item.
PFC
Priority flow control, including over L3, with DCBX and LLDP.
ECN and Dynamic ECN
Early congestion marking, the switch side of the DCQCN loop.
ETS
Enhanced transmission selection to keep RDMA flows ahead.
WRED
Weighted random early detection for queue management.
DLB
Dynamic load balancing with Reactive Path Rebalance and Random Flow.
PFC 死結偵測與復原(Deadlock Detection and Recovery)
Detects paused-queue cycles and auto-drains before jobs hang.
Buffer tuning
在晶片內建共用緩衝區上進行交換器封包緩衝區調校。
RTAG7 hashing
Fine-grained hashing for even spread across the fabric.
gNMI / OpenConfig telemetry
Streaming telemetry over OpenConfig YANG for closed-loop tuning.
What is coming next
The items below are roadmap and upcoming-silicon, labeled as such. They are not shipping capabilities today, and none of the figures are IP Infusion performance numbers.
全域負載平衡 (GLB)
Extends DLB fabric-wide: spines publish path-quality telemetry back to ingress leaves so routing scores the full multi-hop path.
Latency-based ECN
Congestion marking driven by measured latency, adding to the existing ECN and Dynamic ECN behavior.
LLR, CBFS, packet trimming
鏈路級重試、基於信用的流量控制和封包裁剪,用於在鏈路和交換器層面進行丟包恢復與擁塞處理。
Broadcom Tomahawk 6
BCM78910 / BCM78914, 102.4 Tbps, 3nm. Announced by Broadcom. OcNOS support planned.
Follow the evidence further
Each proof point above has a deeper technical page. Compare the transports head to head, size a fabric for your GPU count, or read how the lossless behavior is built.
AI fabric 實證常見問題
乙太網路是否已可用於正式環境的 AI fabric?
在 AI 工作負載上,乙太網路能否與 InfiniBand 相當?
乙太網路在 AI 訓練中已驗證的規模有多大?
OcNOS-DC 目前為 AI fabric 支援哪些功能?
OcNOS-DC 在 Ultra Ethernet(UEC)方面處於什麼位置?
現在可以部署開放的乙太網路 AI fabric 嗎?
以 OcNOS 設計整套 AI 網狀架構
從商業論證到埠數計算,無論您的建置進行到哪個階段,都能從此接續。
深入了解,隨身帶走。
兩份簡短的技術下載,比本頁更深入:完整的 OcNOS-DC 資料表,以及無損 800G AI fabric 架構。
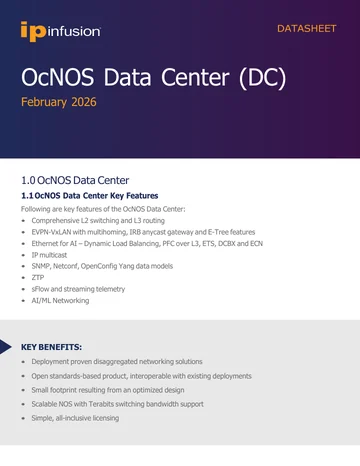
OcNOS-DC 規格書
表單簡短。提交後您的 PDF 將立即在新標籤頁中打開。
✓ 正在新標籤頁中打開您的 PDF……
如果未能自動打開,請使用下方連結。
OcNOS 800G 無損 AI Fabric
表單簡短。提交後您的 PDF 將立即在新標籤頁中打開。
✓ 正在新標籤頁中打開您的 PDF……
如果未能自動打開,請使用下方連結。